Hailuo 2.3 video, Qwen custom training, and Meshy 6 for 3D
Features
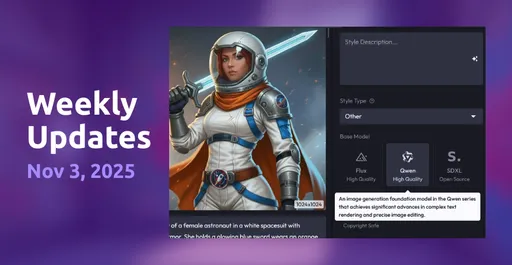
- Custom style training now available with Qwen. Joining our image models for custom training, Qwen from Alibaba Cloud features strong text rendering, layout, and multilingual support.
Bugfix/Improvements
- Fixed a bug that removed UI elements related to uploading a reference image to image generation.
- Added the ability to paste image references directly into the reference image box inside Layer. Always good to save a step!
- Updated the video generation UX so that resolution choice was more obvious and visible - especially important when switching between models.
- Added the ability to generate transparent images once you've removed the background from a generation.
- Added more info details to some of our error messages, to provide context about what went wrong with a generation.
- Added the ability to Prompt Edit specific layers inside the Canvas tool.
New models69
 Video
Versatile video model integrating video and audio creation in one seamless, speed-optimized workflow.
VideoHigh-fidelity video model designed for professional-quality results, offering superior detail and nuanced audio.
VideoHigh-speed T2V variant. Optimized for rapid creation, iteration, and social media content workflows.
VideoPinnacle of Hailuo T2V series. Cinematic quality with superior coherence, detail, and artistic control.
VideoLatest standard video model. Improved prompt understanding and visual consistency for daily creation.
VideoSpecialized model for creating realistic, audio-driven talking avatars with accurate lip-sync and expressions.
 Image
High-quality image background removal.
VideoRemove video backgrounds for advanced video editing.
VideoBria's advanced AI technology designed to increase the resolution of video content efficiently.
 Audio
Multilingual text-to-speech with natural voice selection and stability controls.
AudioGenerate custom sound effects from text descriptions with duration and prompt control.
 Image
Powerful, open-weight 12B image model. Excels in image quality, prompt adherence, and commercial use.
 Image
Open-weight model co-developed with Krea AI. Excels in photorealism and aesthetics.
 Image
12B flow transformer fine-tuned with SRPO for exceptional photorealism and polished composition.
 Image
Open-weight, multimodal model for context-aware image editing. Excels at iterative edits via text.
 Image
Premium model for max editing performance, superior typography, and visual narrative consistency.
 Image
Pro-grade multimodal model for fast, iterative editing, style transfer, and consistency.
 Image
Flagship commercial T2I model offering superior prompt adherence, quality, and stylistic outputs.
 Image
Ultra-fast, open-source model. Generates high-quality images in 1-4 steps for rapid prototyping.
 Image
Next-gen FLUX model. 6x faster with enhanced prompt adherence and top-tier quality for production.
 Image
Delivers ultra-high-res (up to 4MP) images with superior photorealism, detail, and speed.
VideoHighly efficient, open-source I2V model that generates video by predicting the next frame.
 Image
Google's image generation and editing model capable of multimodal reasoning.
 Image
Powerful, versatile OpenAI image model for creative and professional apps.
 3D
Powerful, open-source 3D model producing high-res, textured 3D objects from text or image inputs.
3DLightweight, efficient 3D version optimized for less powerful hardware. Delivers good quality assets.
VideoHigh quality open-source video model from Tencent Hunyuan.
VideoSpecialized model to automatically create and sync sound effects (foley) for video content.
VideoPowerful video model for high-fidelity, imaginative content with complex character motion.
VideoMaster-grade video model. Enhanced realism and physics simulation for cinematic, high-impact clips.
VideoPremium 1080p video model. Maximum visual fidelity, capturing intricate details and lifelike expressions.
VideoRefined Kling model delivering professional-grade 1080p video with improved clarity and motion.
VideoHigh-speed video model. Produces rapid, professional-quality 1080p video for fast-paced content.
VideoFast, efficient open-source I2V model. Animates still images using an autoregressive approach.
VideoAccessible video model. Generates engaging 720p clips from text with good visual consistency.
VideoPremium video model engineered for professional-grade 1080p output, superior fidelity, and smoother motion.
VideoRobust video model producing crisp 768p video. Offers a solid balance of quality and reliable performance.
VideoSpecialized video model. Optimized for a dynamic, live-action feel with naturalistic camera work.
VideoAdvanced video model bringing a still image of a person to life using audio, producing expressive videos.
VideoPowerful, user-friendly video model producing high-quality, stylized 1080p video with consistent motion.
 Image
Open-source T2I model. Excels at high-res images from complex text, notable for clear, stylized text.
 Image
Advanced image editing model. Enhanced performance for fine-grained manipulation.
VideoLarge-scale, state-of-the-art video model for stunning realistic and coherent 1080p motion.
VideoHigh-speed variant of Ray 2, optimized for rapid video creation. Perfect blend of speed and quality.
 Image
Versatile image model for graphic design. Generates legible, stylized text and scalable vector art (SVG).
ImageConvert raster images to vector graphics using Recraft.
3DAdvanced 3D generation model creating high-quality, textured T-pose avatars from a single image.
 Image
Latest open-weight MM-DiT model. Major improvements in quality, prompt following, and text rendering.
ImageByteDance's SeedVR2 model for high-quality image upscaling.
VideoPowerful video upscaling model from ByteDance, optimized for high-quality resolution and fidelity improvement.
VideoVersatile and efficient video model. Optimized for speed and ideal for short clips and rapid prototypes.
VideoHigh-quality video model. Tuned for maximum visual fidelity and broadcast-quality 1080p output.
 Image
Unified architecture for image generation and editing. Allows fluid movement from concept to refinement.
3DOpen-source 3D model creating high-quality objects with realistic materials and geometry from text.
3DIncremental 3D update. Refined performance, improved mesh topology, and texture fidelity.
3DLatest 3D model for production-quality assets with superior textures and clean geometry.
ImageUpscale images with high fidelity or creativity.
ImageVery fast upscaling with good quality.
ImageEnhance image quality with advanced upscaling.
ImageTopaz Generative Enhance for enhanced details.
VideoLegacy video model generating high-definition, long-form cinematic video content.
VideoNext-gen video model with enhanced control over narrative, tone, and shot composition. Includes audio.
VideoFlagship video update: refined control, enhanced visual fidelity, and improved subtle motion details.
VideoSpeed-optimized Veo 3.1 model. Delivers high-quality video rapidly for dynamic workflows.
VideoSpeed-optimized Veo 3 variant for rapid video creation and iteration, ideal for short-form content.
VideoESRGAN model for video upscaling, enhancing resolution and detail.
VideoProfessional-grade video upscaling solution utilizing Topaz AI technology for high-quality enhancement.
VideoState-of-the-art video model. Generates detailed, stylistically diverse clips with fluid motion.
VideoPowerful video model. Optimized for top-tier 1080p cinematic quality and consistency.